Power-Failure Recovery for Embedded Products: A Test Checklist

by mhmd bakri

Define what an embedded product preserves, checks and reports after a power interruption, with a hypothetical machine recovery matrix and practical acceptance tests.

Define power-failure recovery around three decisions: what the product does as power falls, which information remains trustworthy after restart, and what must be checked before operation resumes. Then test interruptions during real work, storage writes and startup. A useful recovery requirement names the expected outcome and the evidence needed to accept it.

This guide is for founders and engineering teams developing embedded devices or machines with electronics, firmware and moving parts. It turns a broad requirement such as “recover after a power cut” into a reviewable specification and a practical test matrix.

1. Choose the recovery outcome for each operation

List the operations a loss of power can interrupt: changing settings, taking a measurement, moving an axis, executing a job, recording completion or installing firmware. Decide separately whether each operation should restart, resume from a verified checkpoint, be abandoned, or wait for an operator.

A monitoring device might resume sampling after validating its configuration and sensors. A machine halfway through a physical process may need inspection before a new cycle. A saved step number can identify where software reached without establishing the position or condition of the mechanism.

For each operation, record:

  • Retained information: the configuration, job identity or checkpoint that must survive.
  • Permitted loss: which unfinished records or work may be discarded, and how that loss is reported.
  • Restart conditions: the electrical, mechanical and application checks required before proceeding.
  • Operator action: what the user must inspect, acknowledge or restart.
  • Failure outcome: what the product does when its saved state cannot be trusted.

Define protective behavior through the product’s risk assessment. Removing drive power can itself create a hazard if a mechanism supports a load. The required response may involve mechanical restraints or other protective provisions. This article addresses recovery requirements; it does not establish machine safety or replace that assessment.

2. Specify behavior while the supply falls and returns

Draw the relevant power domains: processor, external memory, sensors, motor drivers and any separately powered controller. Identify which parts can remain powered when another supply disappears. A USB or debug connection can change a bench test’s power conditions, so record every connected source.

Agree the required output states during reset and before firmware initializes. Review the processor’s pins together with the receiving circuit, including driver enables and external biasing. A software instruction executed later in startup cannot establish what happened during the preceding interval.

Microchip’s AVR brown-out detection documentation illustrates how a voltage-monitoring circuit can hold a processor in reset as its supply drops. It also identifies threshold, hysteresis, restart timing and a minimum detectable pulse duration. Those details are device-specific: check the actual processor, memory and supervisor documentation before selecting thresholds or accepting a short-dip test.

If the design relies on a power-fail warning to finish a write, establish that enough energy remains for the complete operation under the specified conditions. Include the storage device and any other required circuitry. Otherwise, design recovery to tolerate an interrupted write. Do not assume that a shutdown handler will always run to completion.

3. Define exactly when saved data becomes durable

Separate data that must persist from state that can be reconstructed. Calibration and accepted configuration may need preservation; a live sensor reading may become stale immediately after an outage. Identify the storage format, version, validation rules and fallback for every required record.

Then define the commit point: the point at which the application can tell the user that a change has been saved. Check the storage API’s completion and error semantics, including any buffering below it. Treat a failed persistence operation as a visible failure rather than displaying a successful save.

Two primary-source examples show why the details matter:

  • Zephyr’s Non-Volatile Storage documentation describes writing data before its metadata and ignoring entries with missing or incorrect metadata during initialization. Its metadata checksum does not cover the stored data; a separate data CRC is optional and is checked when the complete element is read.
  • The littlefs documentation describes power-loss-resilient file operations and says file updates are committed when sync or close is called. Its underlying storage synchronization must correctly flush cached writes.

These are examples of storage behavior to verify, rather than a prescribed MakersGround technology stack. A filesystem or key-value store does not decide which values your application must accept together. If travel limits, scaling and a configuration version form one valid set, specify how an interrupted update produces a complete accepted set or a defined fault. Test for mixed generations explicitly.

Balance checkpoint frequency against permitted data loss and storage endurance. Use the chosen memory’s specifications, the actual record size and erase behavior, and the expected write rate. Zephyr’s documentation includes a flash-wear calculation, but its example lifetime is specific to its assumptions and should not become a product promise.

4. Reconcile saved progress with the physical product

A physical action and its completion record do not necessarily happen at the same instant. If power disappears after the action but before the record is committed, the restarted controller may be unable to determine whether the action finished. Writing “complete” earlier creates the opposite problem: the record can survive while the physical work remains unfinished.

Decide how the product handles that uncertainty. It might obtain fresh sensor evidence, reject the interrupted work, or require inspection. Keep “outcome unknown” distinct from “not started” and “complete,” particularly when repeating an action could damage a part or perform the operation twice.

For motion, state whether position remains trustworthy after power loss. Any reference-recovery movement needs its own permitted conditions and path; automatically homing a machine can be inappropriate when material or an obstruction remains in place. The user interface should explain what is known, what needs checking and why the cycle cannot yet continue.

For connected products, also reconcile the remote application’s view after restart. A cached “running” or “complete” label should be replaced by current device evidence. The broader hardware–firmware interface checklist covers how to agree command outcomes and data meaning between those layers.

Worked example: a machine that waits after an interrupted cycle

Hypothetical example: a desktop machine has a motorized stage, a saved configuration and a multi-step processing cycle. Its design brief requires an interrupted cycle to be marked for inspection, with no automatic cycle continuation after power returns. This is an illustrative policy, not a description of Gomicron’s firmware, a MakersGround test result or a complete safety design.

The team turns that policy into the following acceptance matrix. Mechanical protection during the outage and the conditions for any later movement must be defined separately through the machine’s risk assessment.

Illustrative power-interruption acceptance matrix
Interruption point Required recovery Evidence to collect
While a configuration update is being stored Load a complete accepted configuration, or enter a configuration fault. Reject a mixture of old and new fields. Stored record, active values, version and displayed outcome after restart.
After a cycle is accepted, before movement starts Report the interrupted cycle and require the defined inspection and new-start procedure. Job identity and state; confirmation that the old cycle does not start itself.
During stage movement Prevent cycle continuation. Treat position as unverified until the defined recovery procedure establishes it. Driver-control signals, observed mechanism behavior and operator instructions.
After physical work, before completion is saved Report an uncertain outcome requiring inspection. Do not silently repeat the work. Physical work state compared with the persistent record and displayed status.
During recovery startup Return to the same controlled recovery process when power is stable again. Repeated-interruption traces; no unintended transition to a running cycle.

A test passes only when the observed electrical, physical and user-visible behavior matches the agreed requirement. Reaching the application’s home screen is just one observation.

5. Test the transitions and preserve the evidence

Use an approved test setup operated by qualified personnel, with guards and protective functions intact. Plan how interruptions will be introduced at the appropriate supply boundary. Do not improvise mains switching or defeat safeguards to reach an internal connection.

Cover complete supply removal, relevant short dips, slow decay and repeated interruptions, using conditions justified by the product’s intended supply environment. Test idle operation as well as writes, motion, startup and recovery. A software reset exercises a different condition from removing power from the processor, storage and peripherals.

Record the actual supply waveform where relevant, the trigger point, connected power sources, unit identifier, board revision, firmware version and storage configuration. Collect reset information, startup logs, output traces, retained data and observed physical state. Preserve failed cases so the repair can be retested at the same interruption point.

Where firmware updates are supported, give interrupted installation its own test set. MCUboot’s design documentation, for example, explains how persisted swap information supports resuming an interrupted image swap. That mechanism is specific to the configured update strategy. Verify the actual bootloader, image layout and recovery procedure used by the product.

Agree test coverage and acceptance criteria before running the campaign. Record repetitions and their conditions; a series of successful restarts does not by itself establish a field failure rate. Keep unresolved cases visible in the release decision.

How this connects to MakersGround’s project work

The historical Gomicron 3D printer engineering record documents MakersGround’s work across mechanical design, PCB electronics, firmware and control, slicing software, prototyping and manufacturing. Its CAD, hardware photographs and software material show a product spanning the disciplines that must coordinate recovery behavior.

That record does not publish the printer’s power-failure architecture or recovery test results. The requirements and hypothetical matrix in this article are general engineering guidance, with no claim that this procedure was used on Gomicron or that the historical project establishes current commercial availability.

What to bring to a power-failure recovery review

  • A power-domain diagram and the selected components’ reset and storage specifications.
  • A list of operations, persistent records and acceptable loss for each.
  • The required behavior during supply loss, startup and uncertain physical outcomes.
  • A definition of when configuration or job completion can be reported as saved.
  • An interruption matrix with observable pass criteria and responsible engineers.
  • The operator recovery procedure and the evidence needed before restarting work.

For a product deployed in Lebanon, the Gulf or elsewhere in MENA, check the intended site’s actual supply, backup-power arrangement and service access. Use those findings to define the tests instead of assuming one regional power profile.

Explore MakersGround’s embedded systems and firmware services and electronics and PCB development, or discuss your product’s hardware and recovery requirements. Leave the review with explicit recovery outcomes and a testable acceptance matrix so the next prototype can answer the important questions.

Technical references and linked project evidence checked on 7 October 2026. The desktop-machine example is hypothetical.
On-Device, Gateway or Cloud AI? A Hardware Decision Guide

by mhmd bakri

Compare on-device, gateway and cloud AI inference for custom hardware using response time, connectivity, power, data handling and maintenance requirements.

Choose the location of AI inference by starting with the decision the hardware must support. Use on-device processing when the complete workload fits the product and must work without a remote connection. Consider a nearby gateway when several devices can share local computing resources. Consider cloud inference when the application can tolerate the connection dependency and remote processing meets its data, response-time and operating requirements.

The right choice may combine these locations. A device can make a local decision while a server handles later analysis. For founders and engineering teams developing custom hardware or industrial monitoring products, the useful deliverable is a tested architecture with explicit failure behaviour and ownership.

What changes between on-device, gateway and cloud inference?

Inference means running a trained model on new input to produce a result. Training and inference can happen in different places. In this guide, on-device means inference inside the sensing product; a gateway is a separate computer nearby, such as an industrial PC receiving data from several sensors; and cloud means inference on a remote service reached over a network.

A gateway that only forwards images to a server is not performing inference locally. Remote servers can also be privately operated, so identify the actual hosting arrangement. Draw the complete data path and mark where the model actually runs. The label “edge” alone does not explain which connection the application depends on.

A starting comparison for custom hardware
Location When to investigate it Main trade-off to test
On-device The product needs an independent local result, and its model can fit the available hardware. Memory, energy and heat inside each unit; update and service arrangements across the fleet.
Local gateway Several nearby sensors can share computing resources over a suitable local connection. Aggregate load, local-network delay and the effect of losing the shared gateway.
Cloud Remote resources suit the workload, and delayed or unavailable results have an acceptable handling path. End-to-end response time, data transfer, recurring operation and network or service outages.

These are candidates to evaluate, rather than guaranteed advantages. A small local processor can be slower than a remote service; a shared gateway can become overloaded; a cloud design can be appropriate for a task that has no immediate deadline.

1. Budget the whole response, from sensor to useful result

Start the clock at the event that matters to the user. A camera application may need image acquisition, preprocessing, transfer, queueing, inference, postprocessing and delivery to an operator. Measuring only the model call leaves much of that path untested.

Define the deadline and the consequence of missing it. Record response-time distributions, slow cases and deadline misses under representative load. A 95th-percentile measurement describes the observed test distribution; it does not establish a maximum response time or a safety guarantee.

For a gateway, test all intended inputs together. For cloud inference, test the actual upload path and service behaviour, including connection setup and retries. For on-device inference, include other tasks that share the processor and memory. Repeat sustained tests in the intended enclosure and operating conditions.

Separate operator advice from machine protection or control. An inspection suggestion can have an explicit “result unavailable” state. A protective function needs its own safety requirements and engineering assessment; this placement checklist does not establish that an AI model is suitable for that function.

2. Define what happens when a connection disappears

Write down which output must remain available during an internet outage. Then remove that connection in a controlled test and observe the entire application. A locally stored model will not make the workflow independent if startup, preprocessing, authentication or the user interface still requires a remote service.

Test local-network loss separately from internet loss. A gateway can continue operating without an internet connection only if its required local inputs and dependencies remain available. Losing the link between a camera and that gateway is a different failure.

  • Current result: define how old an input or prediction may be before it becomes unusable.
  • Unavailable result: show a clear state and the agreed operator response, rather than leaving an old “normal” indication on screen.
  • Stored data: set a buffer limit and an explicit rule for what happens when it fills.
  • Recovery: distinguish delayed records from live events and decide whether old work should be processed or discarded.

Local inference and cloud management can coexist. For example, AWS IoT Greengrass V2 documentation describes deploying models for local inference and separates the model, runtime and inference application into components. That is one product-specific implementation pattern. The application still needs its own dependency and outage tests.

3. Check memory, power and model quality together

A model file that fits in storage may still exceed working-memory limits when it runs. Account for input buffers, intermediate results, the runtime, application tasks and any concurrent processing. Identify the operations the selected runtime and hardware can execute before committing to a custom PCB.

Google’s LiteRT for Microcontrollers documentation describes inference on constrained devices, with a limited set of supported operations and manual memory management. It does not support on-device training. Those are constraints of that runtime, not a promise that a particular vision or sensor model will fit any microcontroller.

If reducing numerical precision through quantization, compare the converted model against the original on representative, held-out inputs. ONNX Runtime’s quantization guidance warns that the transformation can reduce accuracy and that performance gains depend on the model and hardware. Measure both quality and execution on the intended target.

Define quality around the decision: missed events, false alarms, difficult operating conditions and cases that should be sent for human review. A single overall accuracy figure can hide failures in an important class. Keep inference errors and invalid inputs distinguishable from legitimate negative predictions.

For battery-powered hardware, compare energy over a representative duty cycle: sensing, local computation, radio transmission, retries and sleep. Moving inference into the device may change both computation and communication costs. Test peak demand and sustained temperature as well as average consumption; neither “local” nor “cloud” determines battery life on its own.

4. Map the data that leaves each boundary

List raw inputs, extracted features, predictions, diagnostic logs and stored examples separately. State where each is processed, who can access it, how long it is retained and whether support tools export it. A design that keeps normal inference local can still transmit raw images through a debugging feature.

Choose the smallest data flow that supports the purpose and evaluation plan. For example, a monitoring application might send event counts while retaining selected samples locally for an authorized review. Features and predictions can still reveal sensitive information, so reducing file size does not by itself make data anonymous.

Local processing can help meet a requirement to keep particular data on site, but placement alone does not settle security, privacy or legal obligations. Confirm the actual customer’s requirements and destination markets before selecting storage regions or remote-support arrangements.

5. Decide who maintains every deployed version

Plan a release as a compatible set: model, input preprocessing, runtime, application logic, decision thresholds and output meaning. Replacing only the model file can change behaviour if the expected image normalization, sensor scaling or label order also changes.

Record which release each unit or gateway runs. Define who approves an update, how its source and integrity are checked, how installation failure is handled, and how an authorized recovery version is selected. Test those paths before distributing the product. Keep acceptance inputs and expected outcomes so a new release can be compared with the previous one.

NISTIR 8259A’s IoT device cybersecurity baseline includes data protection, interface access and secure, authorized software updates. It provides a starting point for product requirements; applying a checklist does not demonstrate certification or a completed security assessment.

Include maintenance in the cost comparison. Estimate per-unit hardware, gateway installation and replacement, connectivity, remote inference, storage, monitoring and field support over the same operating period. Use the expected event rate and retention policy. A low bill of materials or low price per inference can conceal costs elsewhere in the system.

Worked example: an advisory packaging inspection system

Hypothetical example: a team is evaluating three cameras that flag a missing or incorrectly positioned label for an operator. Assume the design brief asks for a result within one second of capture, continued operation during an internet outage, and raw images to remain on site. These are illustrative requirements, not a MakersGround deployment, measured result or universal inspection specification. Existing machine protection and operating procedures remain separate.

A local gateway is a reasonable first candidate because it could serve the three cameras and keep inference on site. The next experiment is to run the intended model and image pipeline with all three inputs, measuring response times, missed deadlines and quality under representative lighting and product variation. The team must also test camera-link loss and gateway restart.

On-device inference remains a candidate if each camera can meet the quality, memory, power and response requirements independently. Cloud-only inference would conflict with this example’s outage and raw-image requirements. A separate cloud reporting function could still receive approved summary data later, without becoming a dependency of local inspection.

If the gateway fails its tests, record why before changing the architecture. The problem might be image quality, preprocessing, shared compute capacity or network delay. Moving the same workload elsewhere does not automatically fix the limiting factor.

A historical MakersGround example of remote recognition

The Smart Glasses hardware and software project record, originally published in July 2021, describes a wearable camera connected to a mobile application through Wi-Fi Direct. The application sends frames to an online recognition server, receives results, converts them to speech on the phone and returns audio to the wearable.

The record credits MakersGround with device design, hardware and software work. It places recognition on the server and does not assign separate responsibility for developing or operating that server. It provides a concrete example of a workload split across wearable, phone and remote processing, without establishing on-device AI deployment, independently verified performance or current commercial availability.

For a new product, document that split just as explicitly. A connected wearable, local gateway and remote model are different parts of the engineering scope, even when users experience them as one product.

What to bring to an AI hardware architecture review

  1. The decision the prediction supports, its deadline and the consequence of a wrong or unavailable result.
  2. Representative input data, known difficult cases and the proposed evaluation method.
  3. The sensing hardware, memory, power, enclosure and connection constraints.
  4. A data-flow sketch identifying inference location, storage, access and external dependencies.
  5. Expected device count, event rate, update ownership and service arrangements.
  6. A test plan that can reject the preferred architecture if it misses the requirements.

For teams in Lebanon, the Gulf or elsewhere in MENA, gather these facts at the intended site. Confirm the available connection, power, installation access and support responsibilities with the people who will operate the product.

Explore MakersGround’s connected-device development, electronics and PCB engineering, and embedded systems and firmware services, or discuss the hardware and software scope of your product. Start with the required behaviour and the evidence needed to choose an architecture, then agree the implementation scope.

Technical references and linked project evidence checked on 6 October 2026. The packaging inspection example is hypothetical.

Hardware Prototype Revision Checklist: From CAD Change to Test Record

by mhmd bakri

A worked connector-change example shows how to connect CAD, PCB outputs, parts, firmware, as-built units and retest evidence before the next prototype build.

After changing a hardware prototype, prepare a matched set of design and build records, identify what was actually assembled, and connect the revised unit to its test results. The useful question is not simply “Did we update the CAD?” It is “Can someone build and check this revision without guessing which files, parts and software belong together?” Record what changed, what remains applicable and what evidence the next build must produce.

This checklist follows one hypothetical connector relocation through that process. It is intended for product founders and engineering teams preparing another prototype or handing a revised design to a build partner.

1. Identify the unit tested, not a folder called latest

A mechanical model, PCB layout and firmware release can each have a different revision. An assembled prototype can contain a mixture of those revisions, plus rework that exists only on that unit. Give the physical unit an identifier and record its actual configuration before using its results to make a design decision.

A compact record might list the enclosure revision, board revision, applicable parts list, firmware identifier and configuration. Keep the design proposed for the next build separate from the unit already tested. “Latest” does not tell another person which combination produced an observation.

NASA’s configuration-management guidance connects identified baselines, evaluated changes, configuration history and verification. For a small prototype team, those principles can become a short change record and build manifest; the documentation should match the project’s complexity.

2. Separate the observed problem from the proposed fix

Write down the observation before naming the solution. Include the unit, conditions and evidence: what could not be assembled, what measurement differed, or which behavior did not match the requirement. Then state the proposed change and why it might address that problem.

“Move J1” is an instruction. “The mating plug cannot be fully seated with the enclosure fitted; move J1 and verify access on the next assembled unit” connects an observation, a hypothesis and an acceptance check. A drawing change does not demonstrate that the hypothesis worked.

Identify the affected interfaces and who can approve a substitution or deviation. If someone proposes a different connector while building, the decision should be traceable to that proposal rather than disappearing into an informal conversation.

3. Worked example: moving connector J1 on board revision B

This is a hypothetical example, not a documented MakersGround project change. Prototype units P01 and P02 use board revision A. A team proposes moving connector J1 for better enclosure access on board revision B, while keeping the same connector part and net assignments. New unit P03 will evaluate the change. No dimensions or successful result are assumed.

Record Revision decision Evidence needed
Mechanical CAD and drawings Check J1’s new position against the opening, mating plug, cable space and assembly access. Update affected geometry or dimensions. Identified CAD and drawing revisions, followed by the relevant fit and access checks on P03.
PCB sources and outputs Move the footprint and review affected routing. Generate the accepted fabrication and assembly outputs from board revision B. Source revision and output manifest, with agreed units and coordinate origin.
Parts list and assembly instructions The BOM can remain applicable if the actual parts are unchanged. Update instructions where position, orientation or assembly sequence changes. Applicable BOM revision and clear J1 orientation; record any substitute separately.
Firmware and configuration A position change with unchanged electrical connections does not automatically require new firmware. Assess pin mapping and other affected assumptions. Exact applicable software and configuration identifiers, with the reason for keeping or changing them.
Physical build record Preserve P01 and P02 records. Identify P03’s actual construction, parts and any rework. P03’s as-built configuration; distinguish a reworked A board from a newly fabricated B board.
Verification record Select checks for the affected mechanical, electrical and assembly interfaces. Procedure, conditions, observations and decision tied to P03; unresolved issues remain visible.

The table links a design decision to evidence. A reviewed layout or successful export is evidence about the files; it does not prove that the revised physical assembly works.

4. Generate a consistent release pack

Before sending files, identify the source revisions and generate the agreed outputs from them. List the files included, their revision or identifier, and their purpose. Confirm the build partner’s accepted formats, units and coordinate origin. A prototype does not need every possible manufacturing document, but required items should not be inferred from filenames.

The KiCad 9.0 PCB Editor documentation illustrates the distinction between fabrication plots, drill files and component-placement files. These outputs serve different purposes. It is a versioned tool example, not a claim about MakersGround’s software or a universal requirement to use one export format.

If the team uses Git, a release tag can identify a point in source history. Record the commit identifier too: tags can be deleted. A source commit is distinct from the actual firmware bytes installed; recording the binary’s checksum helps identify those bytes, but does not establish functional correctness.

5. Record the intended build and the as-built unit separately

The released pack describes the intended configuration. The build record describes what was actually assembled. Record deviations, substitutions and rework against the unit, including the decision that accepted them or the question still awaiting resolution.

Suppose P03 is assembled using an A board with a connector rework. That may help investigate access, but it is not the same construction as a newly fabricated B board. Label the experiment accordingly. Neither the new CAD filename nor an updated label should erase that distinction.

Keep superseded releases retrievable for the units that used them, while clearly identifying the pack intended for the next build. Historical records should explain an old result without allowing obsolete files to be mistaken for current instructions.

6. Retest the affected interfaces against explicit checks

Choose retesting from the change’s impact, rather than copying an old “passed” result. For the J1 example, relevant questions could include whether the intended plug can be seated, whether the cable and assembly access remain acceptable, and whether affected connections and device behavior still meet their requirements.

Define the procedure, conditions and acceptance criteria before claiming success. Record the exact unit and configuration used, the observed result, and the decision it supports. A fit check on a reworked board answers a narrower question than checking the newly fabricated assembly.

Tests and safe handling depend on the actual electronics and product; this checklist does not prescribe universal powered-test steps. If the change affects pin mapping, timing or command behavior, revisit the hardware–firmware interface agreement as well as the build records.

7. What the historical Gomicron material can show

The Gomicron engineering project documents MakersGround’s work across mechanical design, PCB and electronics, firmware and control, slicing software, prototyping and manufacturing. The original project material provides concrete design context for work spanning these disciplines.

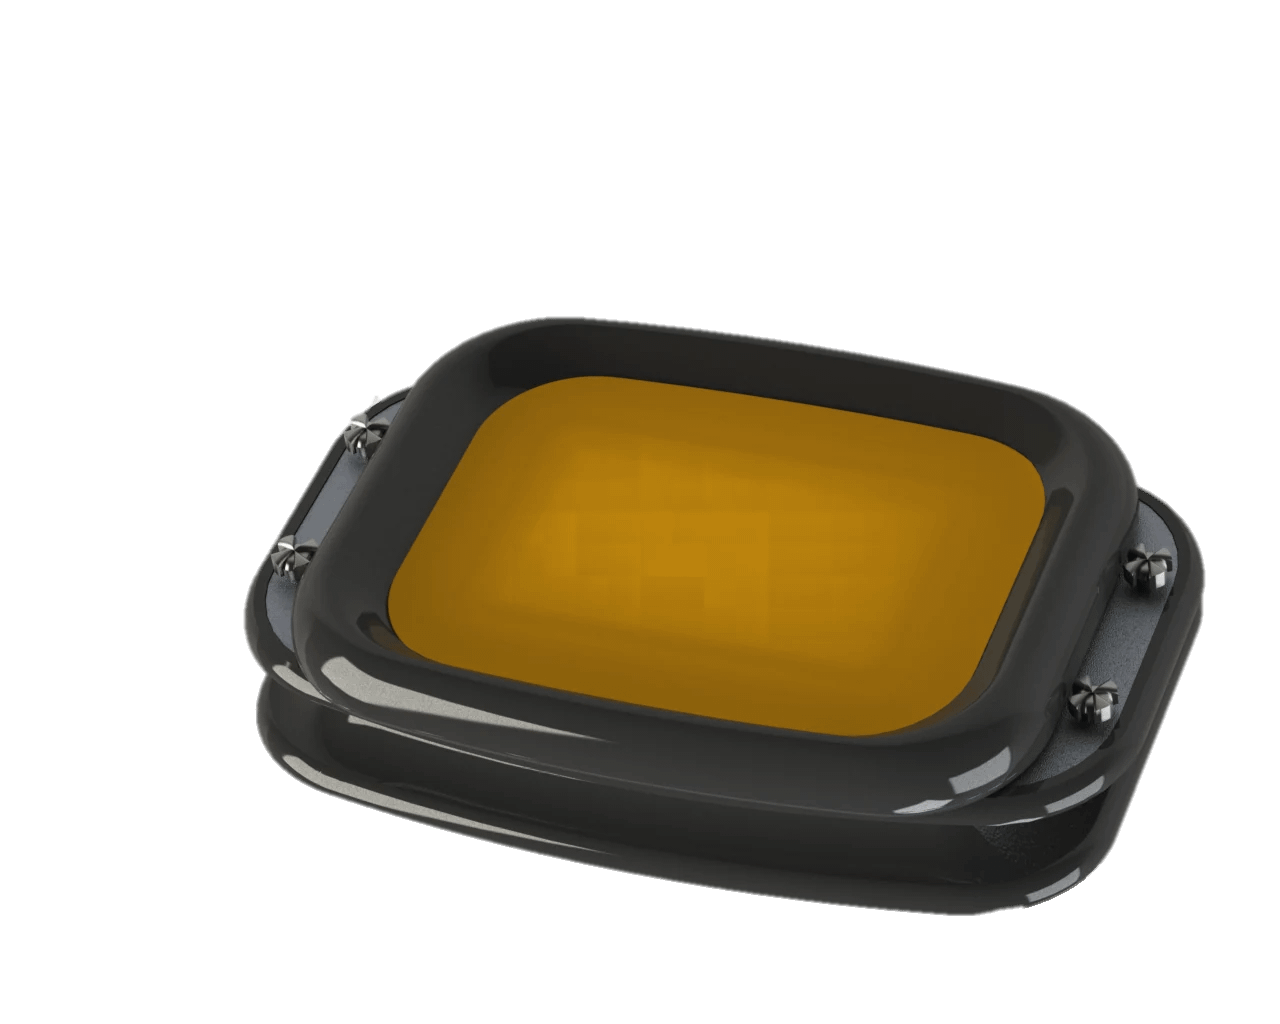
Historical Gomicron printing-tray assembly CAD render
Original printing-tray CAD render from the owner-approved Gomicron project deck, slide 8. The connector example above is hypothetical.

This historical render shows mechanical-design context. It is not a manufacturing drawing, measured fit result or published revision history. The checklist here is a proposed approach, rather than a claim about the release process used on Gomicron.

8. Ask five questions before the next prototype build

  1. Which issue and physical unit motivated the change?
  2. Which design, output, parts and software records changed, and which remain applicable?
  3. Can the build partner identify the intended pack and the decisions needed for substitutions?
  4. How will the actual assembly and any deviations be recorded?
  5. Which checks on which unit will support the next decision?

For a team in Lebanon, the Gulf or elsewhere in MENA, settle file formats, units and document language with the actual build partner. Make approval responsibilities clear when design and assembly happen in different places.

Explore hardware product development and electronics and PCB development, or discuss the next prototype build with MakersGround. Bring the observed issue, current files and unit records so the review starts from the configuration you have.

By Sawsan Sayad. Technical references and linked project evidence checked on 5 October 2026. The connector example is hypothetical.

Hardware–Firmware Interface Checklist for Connected Devices

by mhmd bakri

Define the agreement between electronics, firmware and app teams: electrical limits, data meaning, command outcomes, recovery and version compatibility, with a worked sensor example.

Before integrating a connected device, agree a versioned interface specification covering electrical limits, data meaning, timing, command outcomes, recovery and access. For each boundary, name an owner on both sides and a test that proves the agreement. A connector pinout or message format alone is not enough.

This checklist is for founders and engineering teams coordinating electronics, embedded firmware and application development. It helps turn “these parts should work together” into decisions that can be reviewed before a PCB revision or integrated prototype.

What belongs in an interface specification?

An interface is the boundary where one part of the system supplies something another part depends on: power, a signal, a measurement, a command or a software response. Write down both sides of that boundary. A sensor may report a value correctly while an application interprets it with the wrong units or treats an old reading as current.

NASA’s interface management guidance connects interface control with integration and verification. Its interface requirements outline includes responsibilities, engineering units, tolerances and interface requirements. The checklist below is an original, smaller-scale application of those ideas for connected products.

  • Boundary: which two components exchange power, information or commands?
  • Owners: who maintains each side, and who approves a change?
  • Meaning: what does each signal or value represent, including units and invalid states?
  • Behaviour: what happens at startup, during operation, after a timeout and after recovery?
  • Evidence: which inspection, measurement or integration test will establish that the agreed behaviour occurs?

1. Resolve the physical and electrical boundary first

For a board-to-board or sensor connection, record the connector orientation and pin numbering, signal direction, power requirements, logic levels, reference ground and permitted operating limits. Identify which component provides any required pull-up or termination. Check the selected components’ actual datasheets and bus documentation; a familiar connector does not establish electrical compatibility.

Agree what the pins do before firmware has initialized. Ask what happens if one board is powered while the other is off, if the sensor disconnects, or if reset occurs while a transaction is underway. The answers should be explicit design requirements with a test owner, rather than assumptions left for the first integrated build.

For a product containing moving mechanisms, also identify the coordinate reference, travel limits and responsibility for protective functions. A communication agreement is one part of engineering the system; it does not establish that the machine is safe to operate.

2. Define the meaning of data before choosing its format

For every measurement, specify its name, unit, sign convention, expected range, resolution, validity indicator and sampling rule. Distinguish the time of measurement from the time a gateway or server receives it. Decide how the receiver knows a reading is stale and what it should display when no valid reading is available.

Keep “zero,” “unknown” and “sensor fault” separate where they mean different things. Record where calibration or unit conversion happens so two layers do not apply the same conversion twice. Agree limits on packet size, strings and identifiers before committing to firmware memory allocation.

If using JSON, IETF RFC 8259 describes interoperability issues including duplicate object names and numeric precision. Use unique field names and numerical representations both implementations can support. Successful parsing establishes that a message has an accepted form; it does not establish that its measurement is current or correct.

3. Separate a received command from a completed action

A response saying “received” answers a different question from “accepted,” “applied” or “failed.” Define the states the application can show and what evidence triggers each transition. Include a request identifier so a delayed response can be matched to the command that caused it.

Specify who owns timeout decisions, whether a command may be retried, and how duplicates are handled. Repeating “set the sampling interval to 60 seconds” can be designed to leave the same configuration in place. Repeating “add one unit” changes state again. Those operations need different retry rules.

After a lost connection, the application may not know whether a command took effect. Provide a way to query the device’s actual configuration or command outcome rather than treating a timeout as proof that nothing happened.

A worked example: configuring a sensor’s sampling interval

Hypothetical example: an environmental monitoring device accepts an application request to change its sampling interval. The values and behaviours below are illustrative design choices, not a MakersGround deployment or a description of Gomicron’s firmware.

Contract item Illustrative agreement Acceptance check
Interval and units An integer number of seconds, from 10 to 3,600 inclusive. Reject 0, 9, 3,601 and fractional values; accept the two boundaries.
Request identifier Each new request has an identifier. Retries reuse that identifier and the same payload. A retry produces the same recorded outcome. Reusing the identifier with a different interval is rejected.
Command outcome Report accepted, applied, rejected or failed. Applied means the new interval is durably stored and the sampling task uses it. Check the matching outcome and active configuration. Observe timestamped samples at the agreed interval and project-specific timing tolerance.
Persistence The applied interval survives restart. A repeated request must not change its meaning. Restart after application and verify the interval. Test retry behaviour across restart explicitly.
Unknown outcome If the response is lost, query active configuration. Do not display success based only on a sent request. Drop a response after application and verify the application resolves the state correctly.

The table still needs project-specific decisions: response deadlines, how long request outcomes are retained, who may configure the device, and what happens if persistence fails. Put those decisions in the same specification. Then run the tests with both implementations connected; a simulator alone cannot verify the electrical boundary.

4. Include recovery, access and version changes

Write separate expectations for loss of connectivity, firmware restart and loss of power. Define which settings persist, how invalid state is detected, and how the device reports that it is ready. If readings are buffered, agree their ordering and whether they retain their original measurement time when sent later.

List who can read, configure and update the device, including local service interfaces. NIST’s IoT Device Cybersecurity Capability Core Baseline provides a starting point for device cybersecurity requirements, including interface access and software updates. Apply requirements to the actual product and its operating environment; citing the baseline is not a certification or evidence of a security assessment.

Record hardware revision, firmware version and interface version separately. Keep a compatibility table for the combinations that have actually been tested. Agree how old receivers handle new optional fields and how incompatible changes are detected. A changed unit under an unchanged field name can break meaning even when the message still parses.

What the Gomicron project can show

MakersGround’s Gomicron 3D printer engineering record documents work across mechanical design, custom PCB electronics, firmware, slicing software, prototyping and manufacturing. Original CAD, hardware photographs and software screenshots make those disciplines visible.

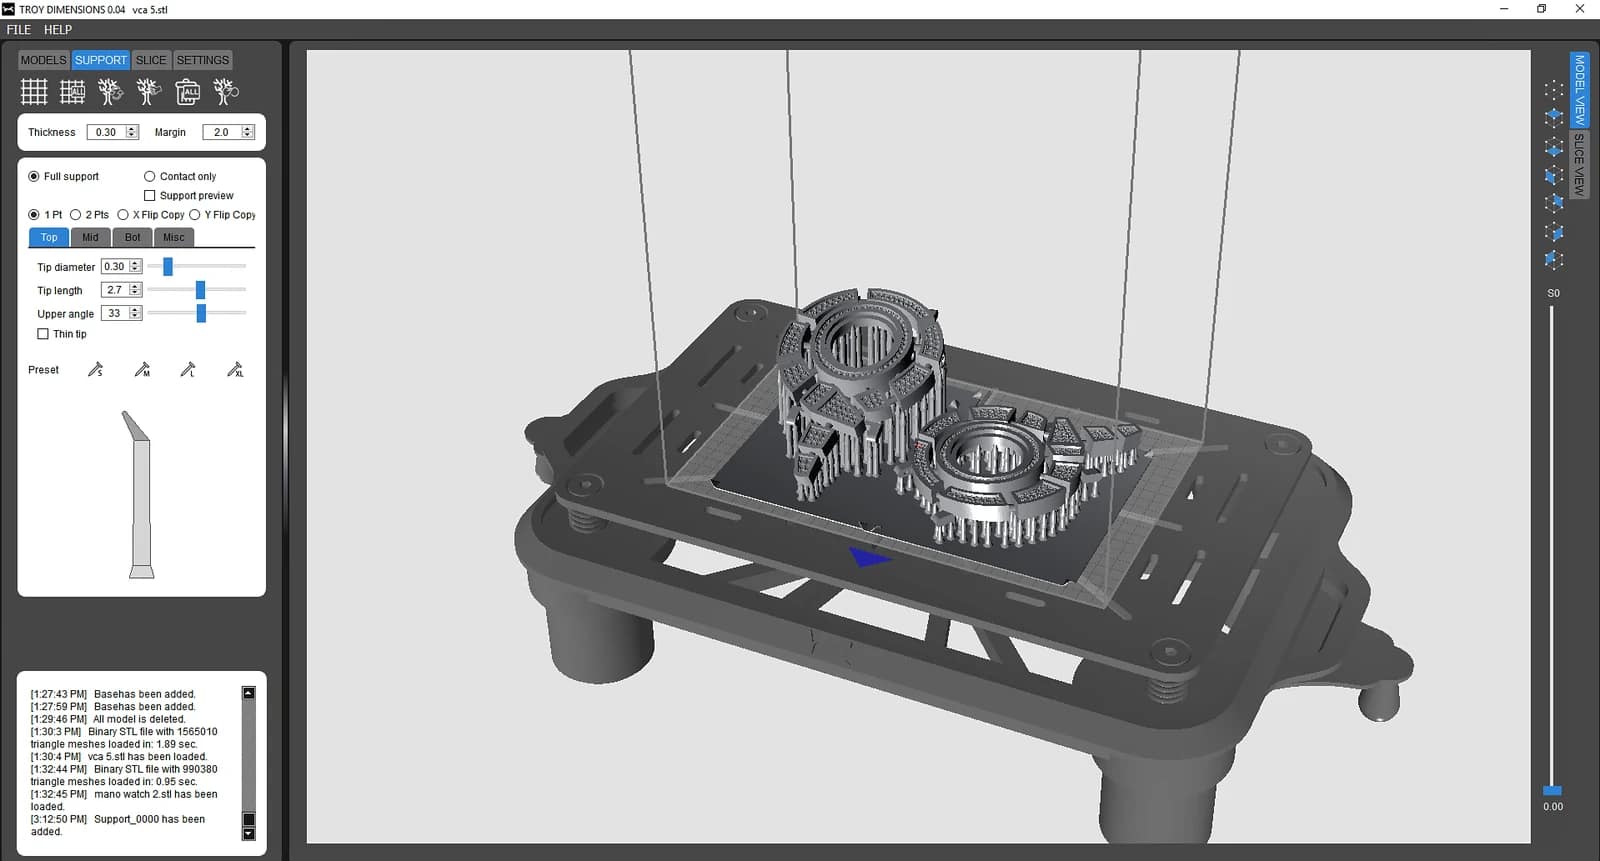
Historical Gomicron print-preparation software showing a model, supports and control panels
Original software screenshot from the owner-approved Gomicron project deck. Its historical window title retains the Troy Dimensions name.

These materials illustrate the scope of a product spanning physical hardware and software. They do not disclose its interface specification, communication protocol, test results or current commercial status. The checklist and sensor example above are general engineering guidance, not a claim that this exact process or protocol was used on that project.

What should you bring to an interface review?

Bring the current schematic and connector definitions, component datasheets, a list of messages and commands, example payloads, startup and recovery expectations, and the hardware/firmware revisions being integrated. Mark unresolved decisions and assign owners. For a deployment in Lebanon, the Gulf or elsewhere in MENA, document the actual site’s connectivity, operator languages, service access and support responsibilities rather than assuming a common regional operating environment.

Finish the review with a versioned specification, named owners on both sides and a short acceptance test list. If you need help defining the boundary between a board, firmware and an application, explore MakersGround’s embedded systems and firmware services and electronics and PCB development, or discuss your existing design and integration questions.

By Sawsan Sayad. Technical references and linked project evidence checked on 3 October 2026. The worked example is hypothetical.

Hardware Prototype vs MVP vs Production-Ready Product

by mhmd bakri

Understand what a hardware prototype, MVP, and production-ready product should prove. Compare the stages and use a decision checklist to choose the next experiment, user trial, or manufacturing investment.

A hardware prototype tests whether an idea can work. A minimum viable product tests whether a limited solution is useful to real users. A production-ready product adds the evidence and processes needed to build, deploy, and support that solution consistently. These stages answer different questions, so a polished demonstration should not be treated as proof that a product is ready to manufacture.

For a team launching in Lebanon, the Gulf, or the wider MENA region, the right next step depends on where the uncertainty sits. It may be sensing performance, user adoption, installation conditions, component supply, or service coverage. Define that uncertainty before buying tooling or expanding the feature list.

Prototype, MVP, and production-ready: the difference

Stage What it should prove What it does not automatically prove
Prototype A technical or design assumption can be tested. Customer demand, repeatable assembly, or field durability
MVP A defined user can complete a valuable task with a limited product. Readiness for unrestricted sales or mass production
Production-ready The defined release can be built, tested, installed, and supported consistently. Suitability for every market, environment, or future feature

When do you need a hardware prototype?

Build a prototype when the next decision depends on technical evidence. Examples include testing whether a sensor detects an event, whether a mechanism carries the required load, or whether an enclosure is comfortable for a user.

A prototype may use development boards, off-the-shelf modules, temporary wiring, or a printed enclosure. Those choices can make learning faster, but the team should identify which parts are temporary and which results are representative of the intended product.

Write the experiment before building: the question, test conditions, measurement method, and pass or fail criterion. Record failures as well as successful runs. If the only objective is “make it work,” a demonstration can conceal the assumption you actually needed to test.

NASA’s technology readiness levels illustrate that laboratory evidence and testing closer to realistic conditions represent different levels of maturity. They are a useful reminder to describe test evidence precisely, rather than using a maturity label as a substitute for it.

When does a prototype become an MVP?

An MVP needs a real user and a complete, limited task. For a connected monitoring device, the useful task might include installation, reading collection, an understandable alert, and a response workflow. A device that sends a number to a screen may be a technical prototype if nobody can act on that number.

Define the smallest scope that lets you test the product’s value. Remove optional features while preserving the requirements necessary for safe, responsible use. A smaller feature set does not remove security, reliability, or applicable product obligations.

Agree the trial setting and its limitations with participants. Observe whether users understand the product, trust the output, and return to it without continuous help from the development team. Collect evidence against the initial hypothesis rather than relying only on enthusiastic feedback.

The MVP decision is whether to continue, revise, or stop. It can expose a weak market assumption even when the underlying technology performs well.

What changes before production?

Repeatable hardware and assembly

Replace temporary construction with controlled design files, a bill of materials, assembly instructions, and a test process. Identify component alternatives and track revisions. Check that manufacturing and servicing decisions match the intended quantities and deployment conditions.

Test units from the intended build process, not only the carefully assembled original. Inspect variation between units and define what happens when a unit fails acceptance testing.

A controlled software release

Record firmware and backend versions, configuration, dependencies, and known issues. Establish provisioning, recovery, update, and access-revocation procedures. A connected product needs an operating plan after delivery, including who responds when devices stop reporting.

The NIST IoT device cybersecurity baseline provides a starting point for defining device security capabilities. Tailor those requirements to the product and document the implemented behavior; a checklist alone is not a security assessment.

Evidence for the intended environment

Specify operating conditions and test against them. For regional deployment, verify conditions at the actual site rather than treating Lebanon, the Gulf, and MENA as interchangeable. Review power, connectivity, installation materials, maintenance access, and the languages needed for instructions and interfaces.

Identify applicable testing and approval requirements for the product and its destination markets with appropriate specialists. Preserve test reports and unresolved limitations. Readiness is specific to a defined release and use case.

A checklist for the next investment decision

  • What is the largest unresolved technical or customer assumption?
  • Which experiment or user trial will provide useful evidence?
  • What result would make us change or stop the project?
  • Which hardware and software parts are temporary?
  • Who owns design files, source code, configuration, and test records?
  • Can another team member build, install, and recover the product?
  • Which risks must be resolved before wider deployment?

Choose the scope with MakersGround

MakersGround’s IoT services include electronics, firmware, and prototyping, while the MVP page describes its MVP offering. Explore existing projects and discuss the evidence your next development stage needs. The scope should follow the uncertainty you need to resolve.

Technical references checked on 2 October 2026.

How to Plan a Manufacturing IoT Pilot

by mhmd bakri

Plan a bounded factory IoT pilot around an operational decision. This guide covers baseline metrics, sensor selection, connectivity, cybersecurity, and measuring value without inventing an ROI forecast.

A manufacturing IoT pilot should test one operational decision on a limited part of the factory, with an agreed baseline and a measurable result. Start with a question such as “Can we identify the cause of repeated stoppages on this line?” Then choose the measurements, connectivity, and workflow needed to answer it.

For a factory in Lebanon, the Gulf, or elsewhere in MENA, the plan must reflect the specific site. Confirm network availability, power quality, equipment access, working languages, and maintenance arrangements locally. The region is not one uniform operating environment, and a vendor demonstration is not evidence that a system fits your plant.

1. Pick a decision, an owner, and a boundary

A pilot needs someone who will use its output. Ask the production or maintenance owner what action a new measurement would change. If the answer is unclear, more sensors may produce more data without improving operations.

Choose a bounded asset, line, or process. State what is included, what remains outside the pilot, and what would justify expansion. For example, a hypothetical pilot could classify stoppage causes on one packaging line before considering other lines. This is a planning example, not a MakersGround client result.

Begin with observation rather than remote control unless the latter is specifically assessed and authorized. Keep safety functions and existing operating procedures intact while you learn how the new system behaves.

2. Establish the baseline before installation

Define the metric and its measurement method. For downtime, record start and end rules, planned versus unplanned events, and who confirms the cause. For scrap, agree the unit, inspection point, and denominator. For energy, distinguish total consumption from consumption per accepted unit.

Record enough context to make a comparison meaningful: product mix, shifts, throughput, maintenance events, and process changes. A lower energy total during a quieter week does not automatically demonstrate an efficiency gain.

Write the pilot’s success and stop criteria before collecting results. Include data completeness, accuracy checks, operator usefulness, maintenance effort, and acceptable disruption. A technically working dashboard can still fail the operational test.

3. Match sensors to the question

Select the signal you need, not the sensor with the longest feature list. Check measurement range, resolution, installation position, environmental suitability, calibration needs, and sampling frequency. A temperature reading useful for a slow process may be unsuitable for a rapidly changing event.

Verify readings against an appropriate reference and document installation conditions. Plan how readings are labeled with an asset identifier, unit, timestamp, and quality status. Missing or suspect values should remain visible rather than being silently treated as normal operation.

Whenever possible, examine existing machine outputs before adding hardware. Accessing controller data still requires approval, interface checks, and a review of any effect on the operating system.

4. Test the network where the equipment sits

Question Pilot check
Is connectivity available? Measure performance at installed locations during normal shifts.
What happens during an outage? Test buffering, reconnection, and clear gap reporting.
How quickly must data arrive? Define an acceptable delay for the operational decision.
Who maintains the connection? Assign responsibility for gateways, subscriptions, and credentials.

Choose wired or wireless connectivity according to installation constraints and observed reliability. Define how device time is maintained and how delayed records are distinguished from current readings. If using MQTT, agree the required message delivery behavior and test it with the application rather than assuming the protocol resolves every outage.

5. Treat cybersecurity as part of factory integration

Inventory devices and data paths, limit access to what each component requires, and agree who can change configuration. Separate the pilot appropriately from other networks, document remote access, and plan credential replacement and software updates.

NIST SP 800-82 Revision 3 explains OT security in the context of performance, reliability, and safety. Use it to frame the plant’s review. An IT change that is convenient in an office may need a different deployment and testing approach around production equipment.

Include the operating team in security decisions. They need a recovery procedure, ownership of alerts, and a way to disable or remove the pilot safely if it causes problems.

6. Measure value without inventing an ROI

Calculate value from observed, attributable changes and agreed unit costs. Compare avoided downtime, reduced scrap, or verified labor savings with the costs of sensors, installation, software, connectivity, training, and ongoing support. Count costs consistently over the same evaluation period.

A practical net-value calculation is measured benefit minus pilot and operating costs. Percentage ROI divides that net value by the included costs, then multiplies by 100. Document assumptions and uncertainty; a small pilot may not provide enough evidence for a credible annual forecast.

Finish with an expansion decision and a list of unresolved issues. A useful result may be “collect better baseline data” or “change the installation,” rather than immediate rollout.

Plan the next step with MakersGround

MakersGround publishes industrial machinery and automation services and IoT development services. Review the existing project portfolio, then share your process, equipment, and pilot question to define a practical scope.

Technical references checked on 2 October 2026.

How IoT Product Development Works: From Idea to Deployment

by mhmd bakri

A practical guide to the phases of IoT product development, from defining the problem and testing technical risks to field pilots, deployment, and support. Learn what each phase should deliver and what evidence to request.

IoT product development turns a physical problem into a connected system that people can operate and maintain. The work usually moves through discovery, technical validation, integrated development, a field pilot, and deployment. Each phase should end with evidence and a clear decision, rather than a demonstration that merely looks finished.

For teams building products for Lebanon, the Gulf, or the wider MENA region, discovery should identify the actual deployment sites. Check indoor or outdoor use, heat and dust exposure, available networks, installation access, and operator languages. A prototype tested in one office does not establish suitability for every site in the region.

An IoT product includes more than a sensor and an app. Its electronics, firmware, connectivity, backend, user interface, and operating procedures need to work together. This guide explains what to ask for at each stage and how to judge whether the next investment is justified.

What should each development phase deliver?

Phase Main question Useful deliverable
Discovery What problem are we solving? Requirements, constraints, and acceptance criteria
Technical validation Can the risky parts work? Prototype results and an architecture decision
Integrated development Does the whole system work together? Testable hardware, firmware, and software release
Field pilot Does it work where it will be used? Observed performance and an issue register
Deployment Can we install and support it repeatedly? Release package, installation process, and support plan

1. Define the problem before choosing components

Start with the user, the environment, and the action the product should enable. A warehouse temperature monitor, for example, needs a defined measurement range, an agreed alert condition, and someone responsible for responding. “Send readings to a dashboard” leaves those decisions unresolved.

Record power availability, physical access, installation restrictions, connectivity, data retention, and expected maintenance. Separate essential outcomes from optional features. Turn requirements into observable checks: what happens when power returns, when a reading is missing, or when the network is unavailable?

The discovery handoff should include a system boundary diagram, a prioritized requirement list, a risk register, and acceptance criteria. Project estimates should follow these constraints; a universal development schedule cannot account for every hardware product.

2. Prototype the uncertainties first

A prototype is useful when it answers a specific question. Can the sensor distinguish the signal from background noise? Can the enclosure fit the installation space? Can the device communicate from the intended location?

Choose experiments around the hardest assumptions. Development boards and temporary enclosures can be appropriate here because the goal is learning. Record test conditions and limitations alongside results. A successful bench test does not establish field reliability or manufacturing readiness.

Before committing to a custom circuit board, review component availability, power consumption, interface compatibility, and alternatives. Preserve the reasons for each choice so later changes do not depend on someone’s memory.

3. Build one complete path through the system

Develop a usable slice from physical input to user action. That might mean a sensor reading, a timestamped message, backend validation, a stored record, and an alert that an operator can acknowledge. This exposes integration problems earlier than building each layer in isolation.

Specify device identity, message format, units, timestamps, and versioning. Decide how the system handles duplicate, delayed, and invalid messages. MQTT is a standardized publish/subscribe messaging protocol often considered for connected devices. Its delivery options still require application-level decisions about stale readings, duplicate handling, and user-visible failures.

Security belongs in the design. NISTIR 8259A identifies core device capabilities including identification, configuration, data protection, access control, software updates, and cybersecurity state awareness. Use the baseline to develop requirements for the actual use case; citing it does not certify a product.

4. Test a field pilot, including failure conditions

Deploy a bounded pilot with agreed entry and exit criteria. Observe real installation conditions, operator behavior, and maintenance demands. Compare readings with a suitable reference and record missing data, false alerts, reconnect behavior, and battery or power issues.

Test recovery as deliberately as normal operation. Disconnect a device, interrupt connectivity, restart the backend, and try an unauthorized request in an approved test environment. Define security test scope using a resource such as the OWASP IoT Security Testing Guide, then document findings and retest repairs.

The pilot should produce a release decision: proceed, revise, or stop. Unresolved risks need an owner and a treatment plan, even when the demonstration is successful.

5. Prepare deployment and the operating handoff

A deployment package should make repeat installations possible. Include hardware revisions, firmware versions, configuration instructions, provisioning steps, test records, and recovery procedures. Agree who operates the backend, manages credentials, receives alerts, and approves updates.

Plan component replacement and product retirement as well as launch. Teams need to know how a device is removed from service, how its access is revoked, and what happens to stored data.

What should you bring to an IoT development discussion?

Bring the problem, intended users, operating environment, existing equipment, and examples of the decisions the data must support. Useful drawings and sample data help; a complete technical specification is not required to begin defining the project.

MakersGround’s published IoT and robotics services cover electronics, firmware, prototyping, and short-run manufacturing. Explore the project portfolio for existing work, or discuss your product requirements to establish an appropriate scope.

Technical references checked on 2 October 2026.